Press & News · Page 2
What is happening at PLANET AI.
-
 Digital document capture: from paper and PDF to usable data What digital document capture is, how it works step by step and what matters in text recognition
-
 Digital inbox: how incoming mail reaches the right desk automatically From the mailroom to the case file: what a digital inbox does, how it works and what to look out for
-
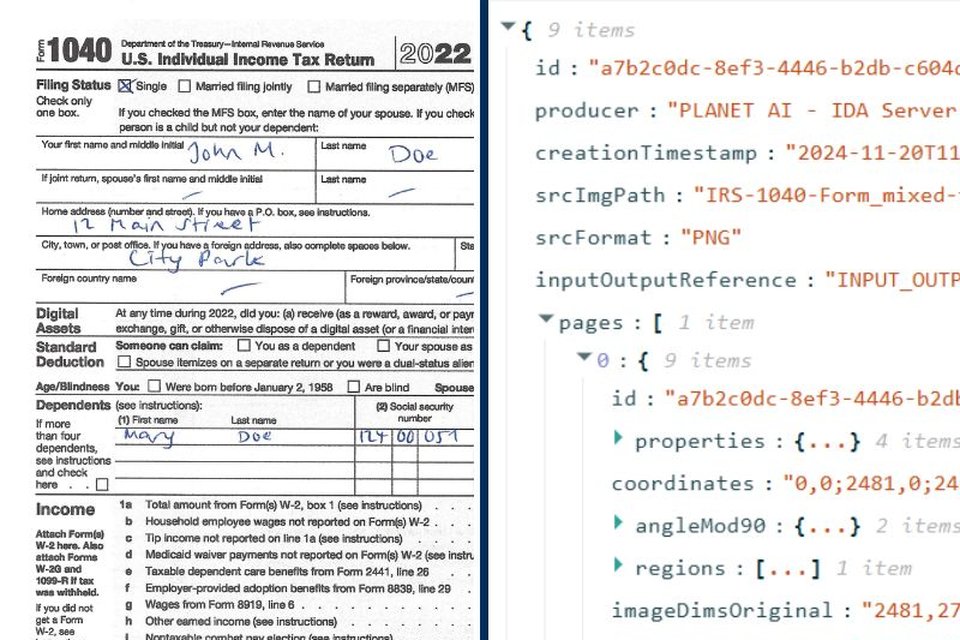 Structured data: how unstructured documents become usable information What separates structured from unstructured data, how document processing bridges the gap and why the output format matters
-
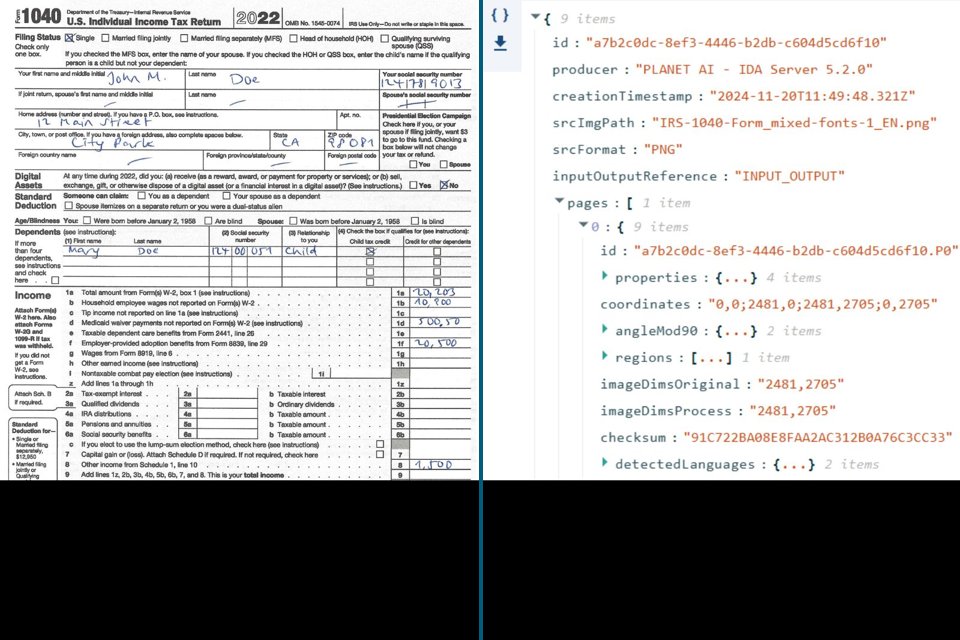 PDF vs. JSON: which format document processing needs, and when Why PDF is made for people and JSON for systems, and why good document processing delivers both
-
 Document automation: what software takes over and what stays with people From capturing and sorting to reviewing and preparing decisions: two stages of document automation, explained
-
 Smart Country Convention: October 15–17, 2024 in Berlin We are taking part in the Smart Country Convention in Berlin from 15 to 17 October 2024, together with Bechtle
-
 IONOS Summit: September 19, 2024 in Berlin We are thrilled to be participating in the IONOS Summit in Berlin on September 19, 2024, together with Bechtle
-
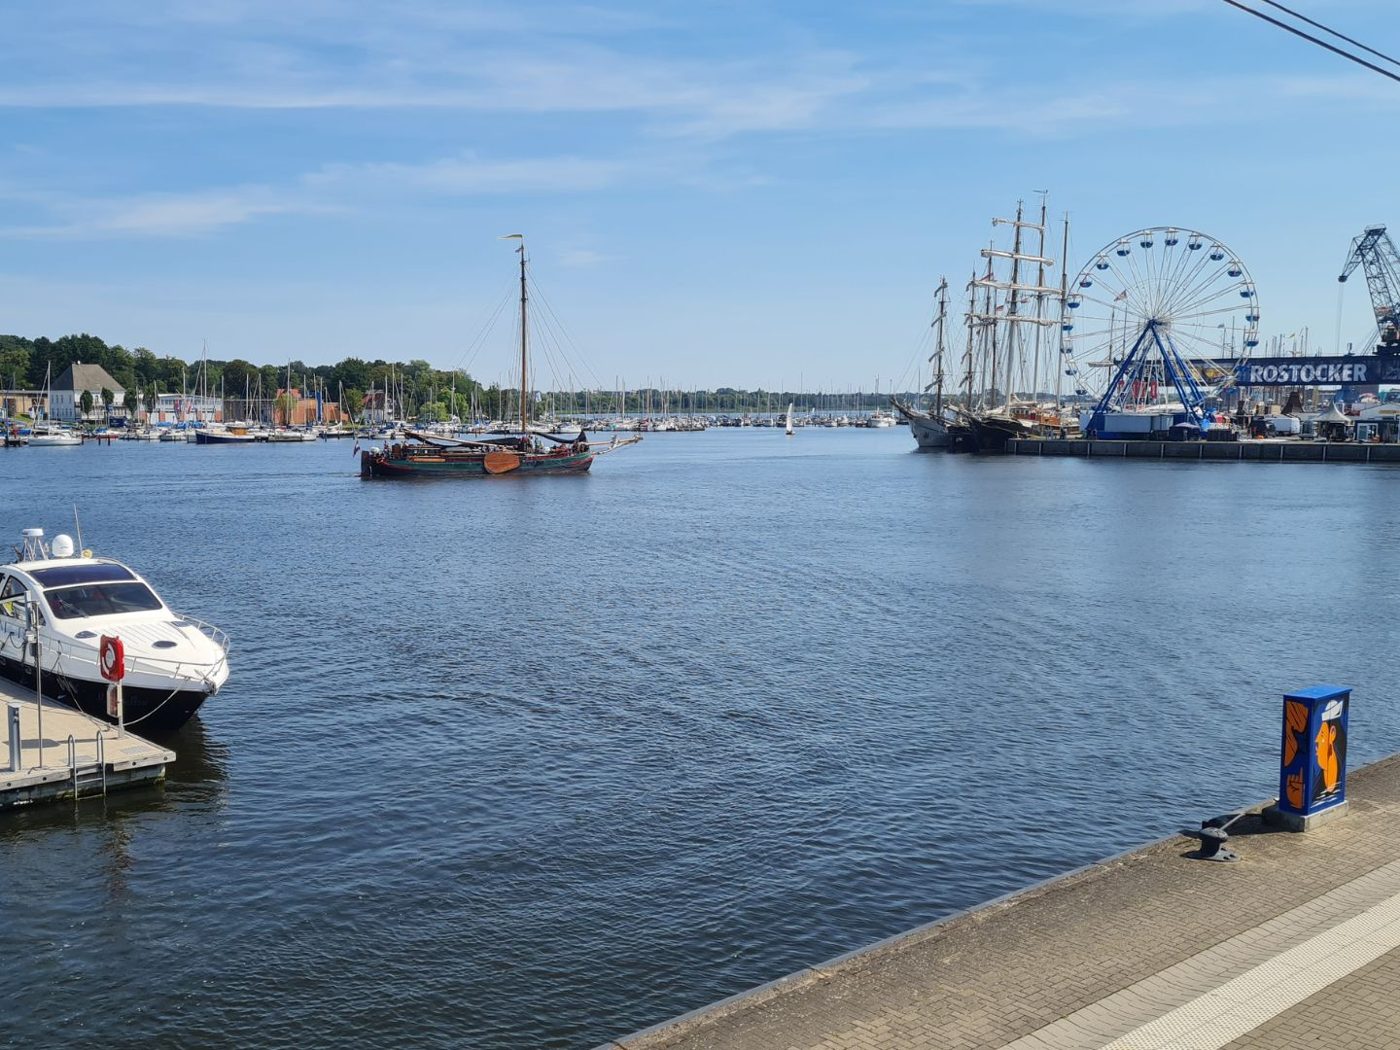 33rd Hanse Sail: Work where others go on vacation Today, on August 8, 2024, the time has finally come: the starting signal for the 33rd Hanse Sail in Rostock & Warnemünde is fired, and we are in the midst of it all, not just mere spectators
-
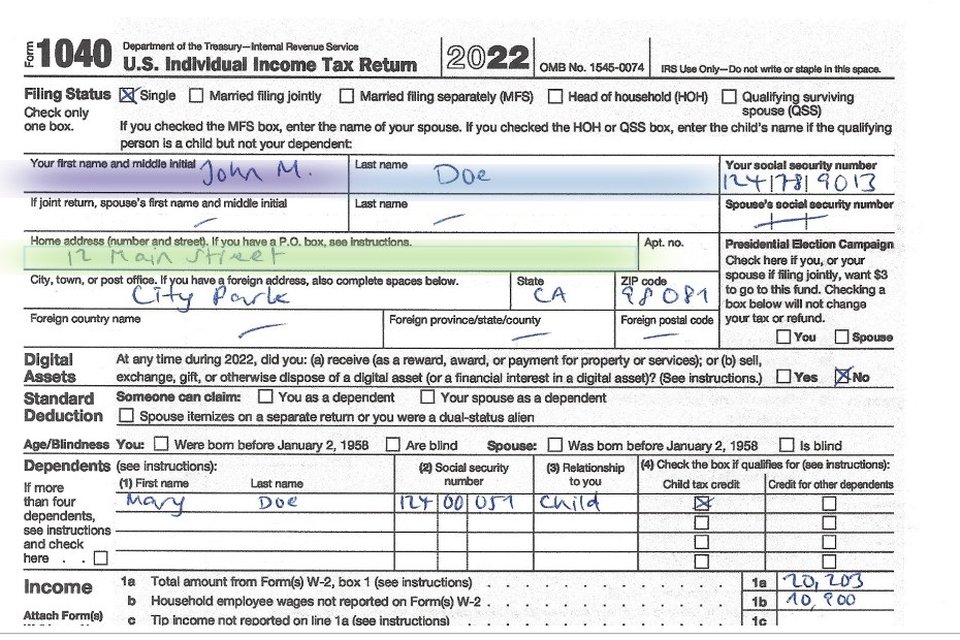 Entity extraction: how software finds names, dates and amounts in documents What entity extraction is, why it depends on good text recognition and how IDA reads both forms and free text
-
 Workflow automation with documents: seven hurdles and what helps Why documents are often the bottleneck in automated processes and how intelligent document processing clears the way
-
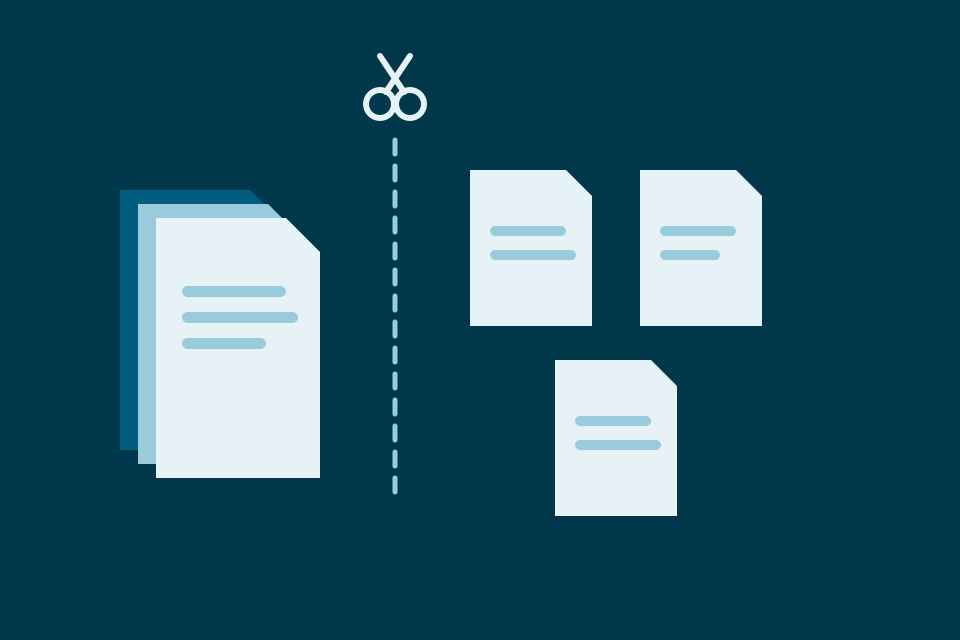 PDF splitting: how software separates scanned batches into individual documents Why one PDF often contains many documents, how AI finds where one ends and the next begins, and where this saves time
-
 PDF data extraction: how information from PDFs becomes usable data Why copying text out of a PDF is not enough, what makes extraction difficult and how IDA delivers the values your process needs