Press & News · Blog
What is happening at PLANET AI.
- LLM Wrapper vs. Agentic Workflows: Why Architecture Matters More Than Model Size How to tell genuine agentic architecture from API cosmetics, with a checklist for evaluating IDP solutions
-
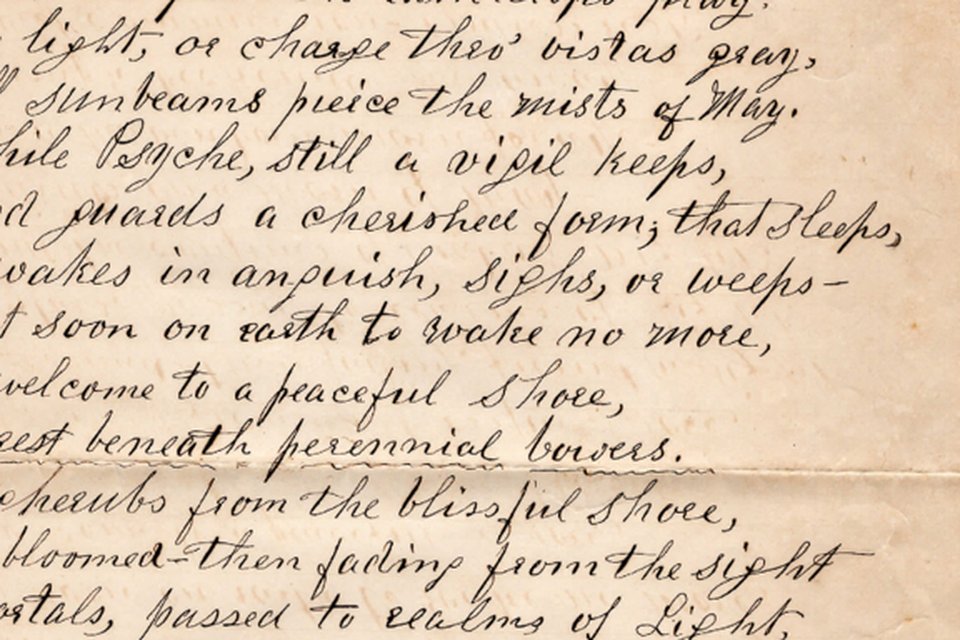 Handwritten text recognition (HTR): making historical handwriting searchable Parish registers, minutes, letters in Kurrent and Sütterlin: how AI turns scanned handwriting into text you can search
-
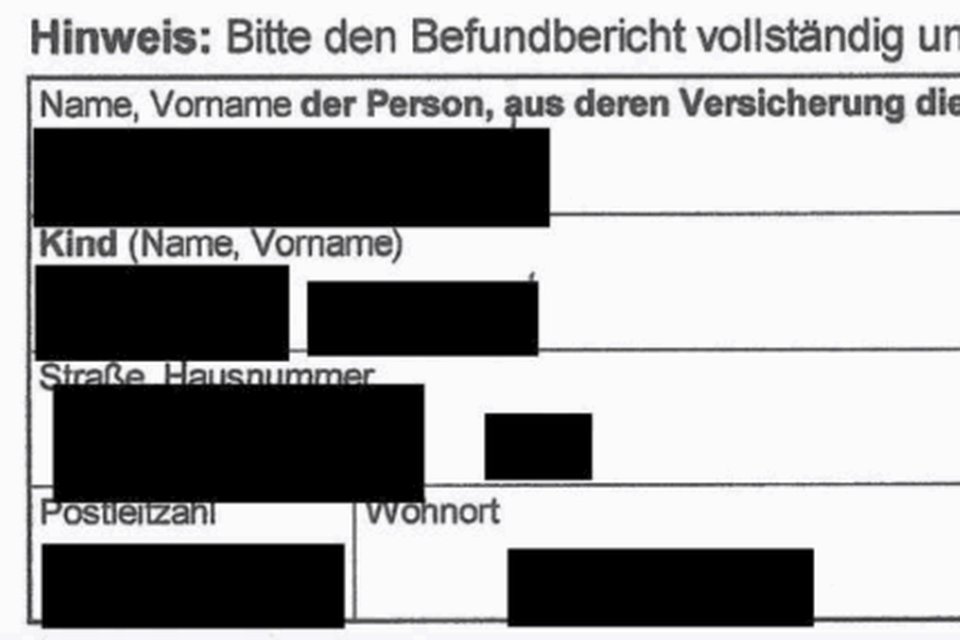 Redacting PDFs with IDA Sensitive data blacked out automatically, not page by page by hand
- The EU AI Act at a Glance: Responsible AI with PLANET AI What the EU AI Act means for companies, how AI systems are classified and how PLANET AI approaches it. A guide for customers and partners
-
 Digital document capture: from paper and PDF to usable data What digital document capture is, how it works step by step and what matters in text recognition
-
 Digital inbox: how incoming mail reaches the right desk automatically From the mailroom to the case file: what a digital inbox does, how it works and what to look out for
-
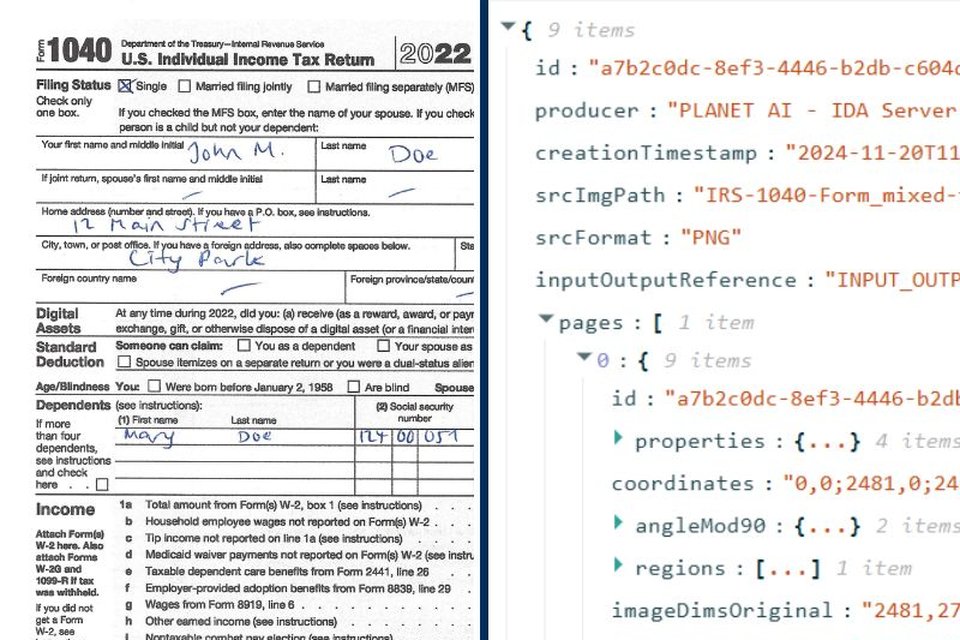 Structured data: how unstructured documents become usable information What separates structured from unstructured data, how document processing bridges the gap and why the output format matters
-
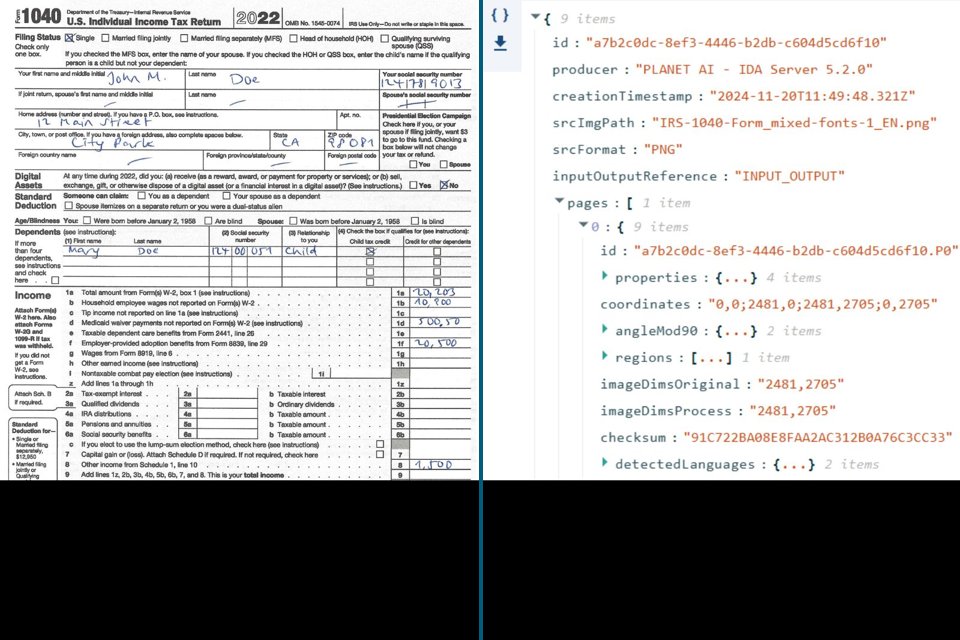 PDF vs. JSON: which format document processing needs, and when Why PDF is made for people and JSON for systems, and why good document processing delivers both
-
 Document automation: what software takes over and what stays with people From capturing and sorting to reviewing and preparing decisions: two stages of document automation, explained
-
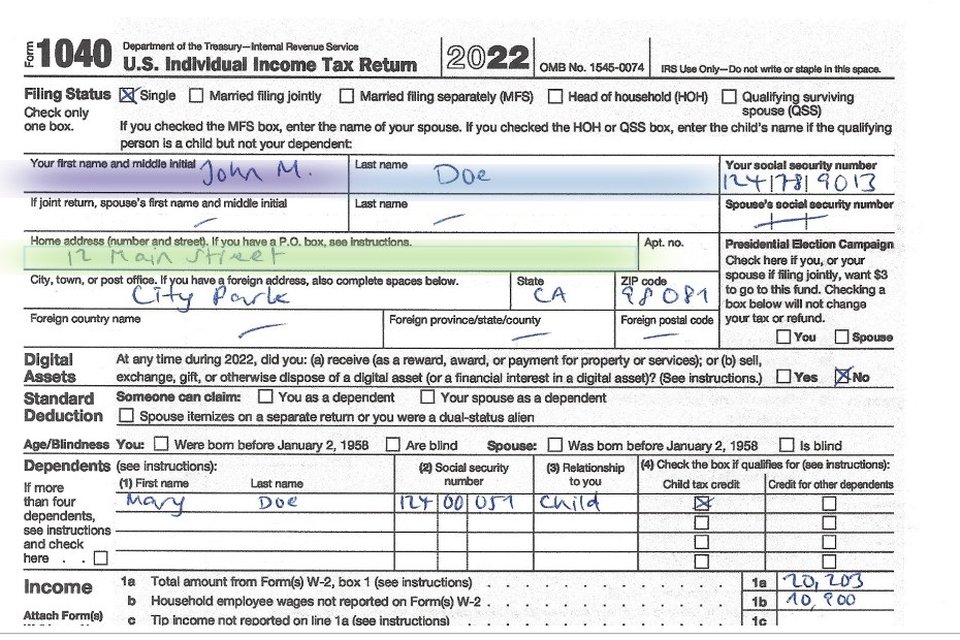 Entity extraction: how software finds names, dates and amounts in documents What entity extraction is, why it depends on good text recognition and how IDA reads both forms and free text
-
 Workflow automation with documents: seven hurdles and what helps Why documents are often the bottleneck in automated processes and how intelligent document processing clears the way
-
 PDF classification: sorting documents automatically How AI assigns every incoming PDF to the right document class, and what that saves in day-to-day work