IDA is the ultimate solution to all your document capture and processing woes! Whether you’re dealing with structured or unstructured documents, handwritten or machine printed texts. IDA has got you covered.
| Feature | Figures (2023) |
|---|---|
| Capture every text | 99 % machine printed, 95 % handwritten |
| Classify captured documents | 94 % accuracy, individually trainable |
| Extract any content | 1-5 sample documents, individually trainable |
What’s new?
Data Extraction & User Experience
Document Split
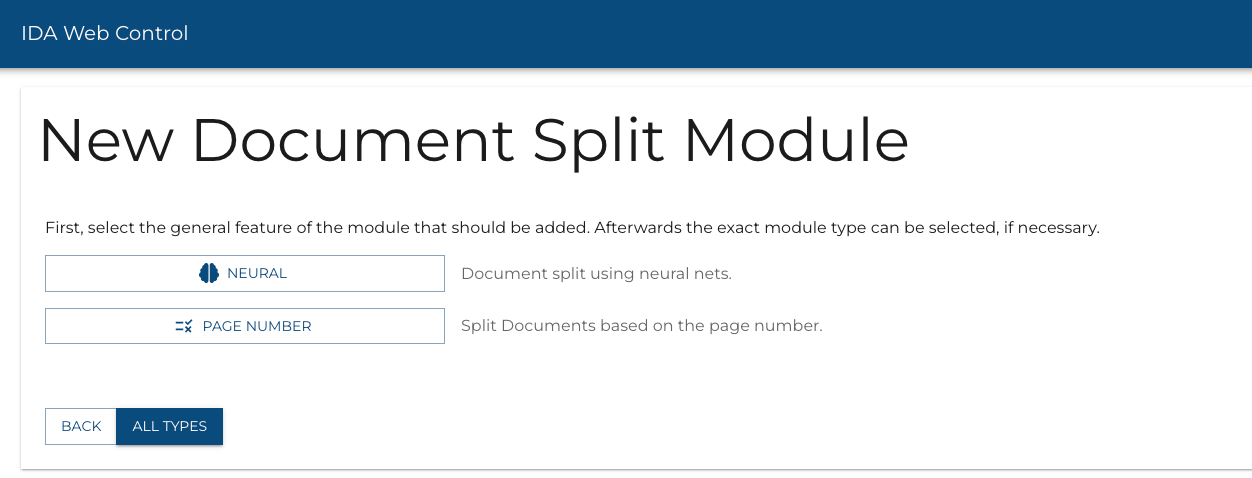
Scanning large document batches can be tough, especially with long PDFs containing over 100 forms in a row. Our new document splitting feature uses a neural net to detect the start and end of multi-page documents or split them based on a fixed number of pages, reducing manual effort. The split documents can then be directed for downstream processing.
Model Training Improvements
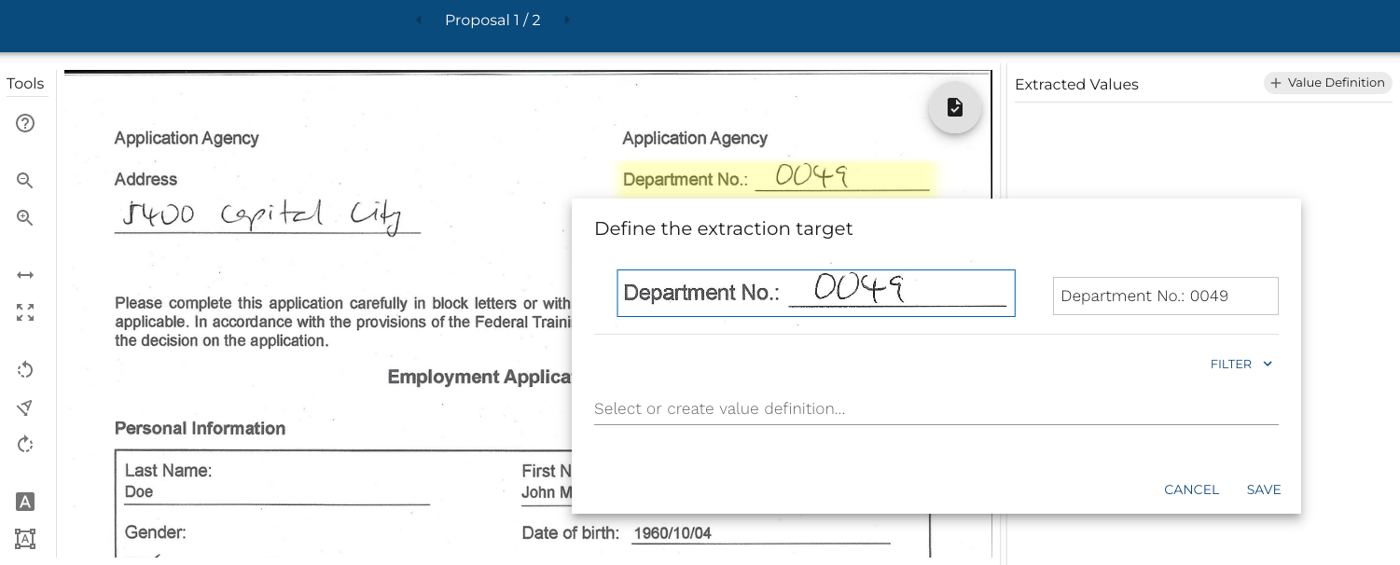
Training with the Extraction Assistant (ExA) is now accelerated by automatic pre-training and the ability to define extraction values “live” on the first document. To make things easier, ExA allows you to use existing AcroFields as extraction values to simplify the data labeling process.
What Else?
Entity Finder Module
In some cases, users need to determine at a glance if a document contains a certain word or number. That’s where our new Entity Finder module comes in, highlighting words in PDFs and JSONs based on a pre-set dictionary or plain text file.
Web client overhaul
Lastly, IDA 5.1 includes a significant overhaul for the Web Client, our workflow demonstration tool. You can now select modules from your active workflow for sample processing.
What’s Next?
OCR Improvement
You can look forward to a new text finder that will further enhance our document capture capabilitites.
Feature Enhancement: Extraction
IDA 5.x will focus on pushing data extraction capabilities like table extraction and unstructured data extraction to the next level.